AI Visibility Measurement Your Board Will Actually Accept
Exposure inside AI answers is rising while attribution collapses. Build AI visibility measurement on presence, share of answer and Philippine sentiment.
AI visibility measurement is breaking because the category keeps selling it as a traffic channel while the traffic evidence collapses. Exposure inside AI answers is real and rising; session-level attribution does not hold. For a Philippine communications lead, the usable move is to grade presence, share of answer and sentiment on a repeating cadence, read by a party with nothing to sell inside the result.
The settled view this week was that the AI-visibility category had been caught out. Three studies landed inside seven days showing AI assistants send almost no traffic, and the easy reading was that the whole thing is a distraction. The messier reading is the correct one. Exposure inside AI answers kept climbing in the same evidence that demolished the traffic case, and both findings stand. What broke was not the channel. It was the unit of proof, and that distinction decides whether your AI visibility measurement line survives its next board review.
Four Assistants, Four Different Answers
Filipino audiences are already inside these systems in volume. A promotional newswire item in The Manila Times on a Philippine AI-readiness test cites Digital 2026, vendor research from Meltwater and We Are Social with mid-2025 fieldwork, putting 42.4% of Filipino internet users aged 16 and over as having used ChatGPT in the past month, sixth in the world. Google rolled out Ask Maps here in September. How brands end up inside those answers is already covered in Media Meter's guide to AI search visibility.
The answers themselves are unstable. ChatGPT, Claude, Gemini and Perplexity disagreed on the leading software brands in four of five categories, according to a study of 2,720 assistant answers over four weeks, 170 buyer-style questions per assistant per week from 13 September to 4 October. Zendesk was the only brand ranked first by all four. Churn was the sharper finding: 79% of question-and-assistant combinations, 536 of 680, changed at least one recommended brand across the four tests, and only 144 returned the same list every week. Read the provenance with the result. The study came from Envoyra, an AI-visibility platform, published by Search Engine Land, which is owned by Semrush.
A single snapshot is close to meaningless at that rate of movement. Any AI visibility measurement you buy has to read on a fixed cadence, because a one-off audit of a system that reshuffles four times a month measures the week, not the brand.
Why the Traffic Case Collapsed in a Single Week
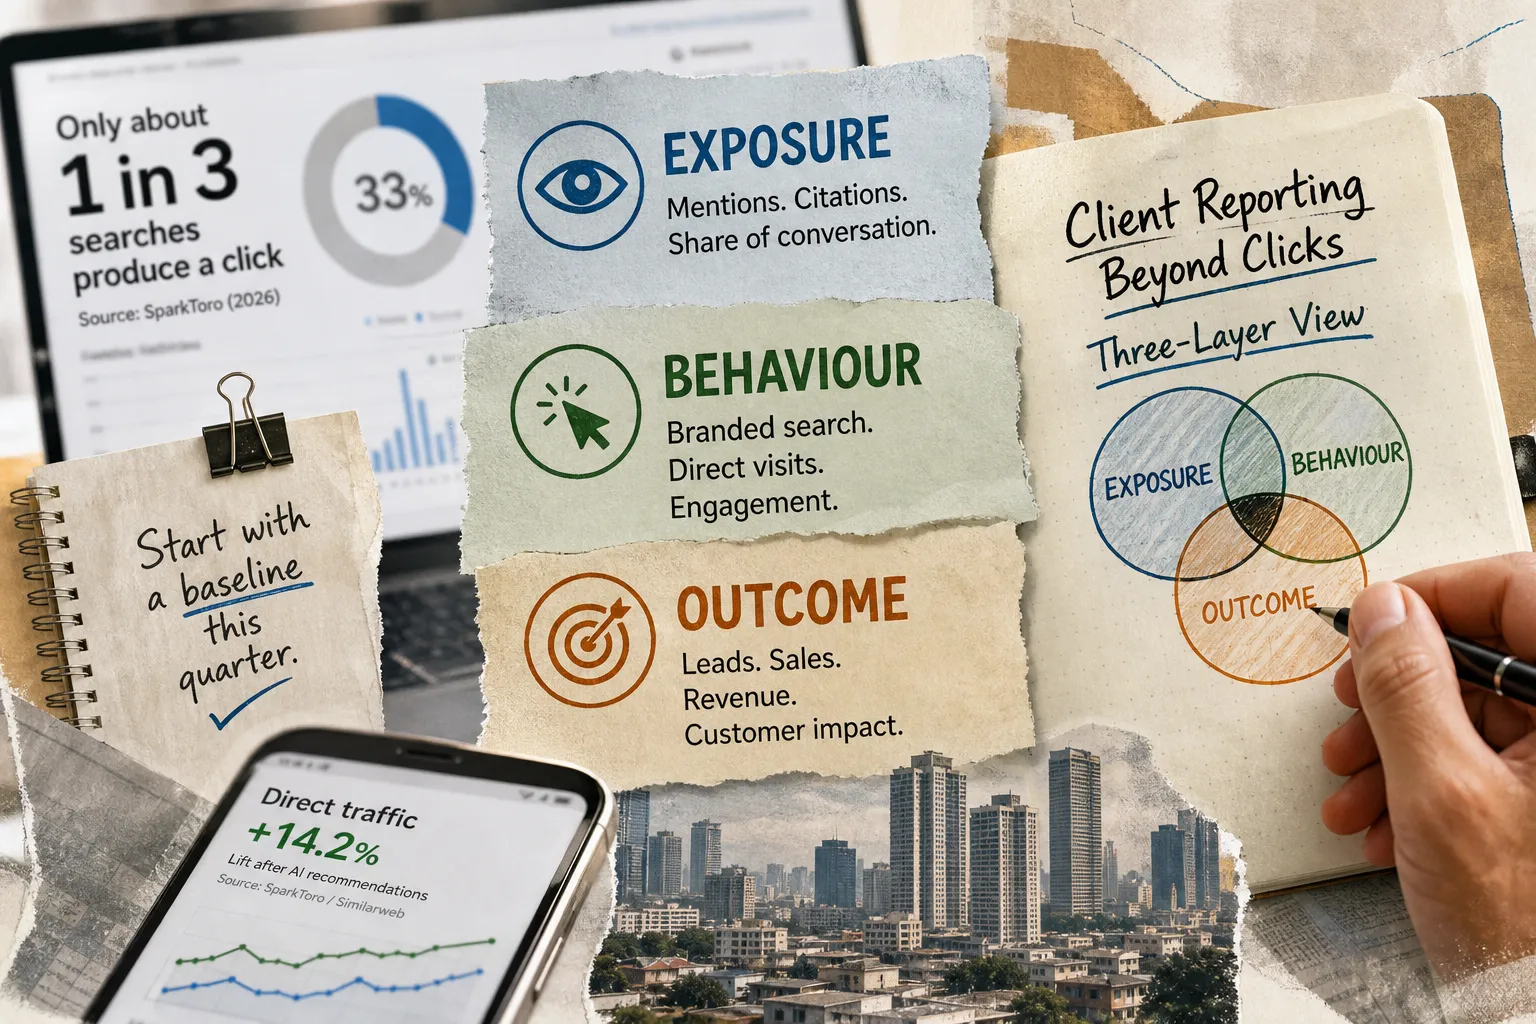
The traffic argument fell apart convincingly. Search Engine Roundtable's roundup of three studies reported ChatGPT sessions at 0.62% of Google organic volume across 12 months, 100 sites and 145 million sessions in Marie Haynes's GA4 analysis. ChatGPT visitors converted far better, 13.8% against 3.02%, and it barely registered: Google still drove 96.5% of total conversions and 27 times more than all large language models combined. SEO Works put organic search at 39 times the traffic of AI assistants. Kevin Indig found no reliable relationship between AI visibility and branded search or direct traffic across 12 sites.
SparkToro's read of the same studies puts all assistant referrals at roughly 0.73%, below DuckDuckGo, and lands on the reframe worth keeping: AI is a brand channel, "a digital billboard" in Mike King's phrase, to be invested in and measured as one. SparkToro sells audience-research tooling, so take the framing and weigh the interest. Judging a billboard by the drivers who pulled over would understate it badly, which is roughly what a session report does to a brand channel.
The split already shows up locally. A year-long study of 80 Philippine brands across seven sectors found mentions of PH brands in Google AI Overviews rose more than twentyfold during 2025 while organic branded traffic across those same 80 websites fell between 3% and 8%. It explicitly did not establish cause and effect. The work came from Truelogic, which sells AI search optimisation and drew on 40 of its own client projects. "Being found is no longer just about ranking for the right keywords," managing partner Bernard San Juan III told BusinessMirror.
Exposure is the half that keeps growing. Semrush recorded AI Overviews on 88% of the commercial keywords it tracks, up from 45.75% a year earlier and 97% when weighted by search volume, with e-commerce keywords climbing from about 33% to 85% and review searches from 30% to nearly 90%. Search Engine Land's write-up is clear about the limits, and they travel with the number: 400 US desktop keywords, three industries, no measurement of clicks or conversions. Nothing we could source tests whether Philippine commercial queries trigger AI Overviews at anything near that rate, which is itself the argument for a local reading rather than an imported American one.
Presence, Share of Answer, Sentiment: The Units That Hold
So let's be concrete about what replaces the session count. Presence asks whether the brand appears in the answer at all, per assistant and per question type. Share of answer asks what proportion of relevant answers name you against named competitors. Sentiment asks how you are characterised when you appear, which here means reading Filipino, English and the Taglish register in between. Automated sentiment across Philippine registers is improving, not solved, so that read stays directional and a board paper claiming otherwise is overclaiming.
Philippine brands are already graded on the middle unit. The same Truelogic study reports a leading Philippine bank at 38.1% AI share of voice, highest in its peer group, and a major property developer at 53.38% across Google AI Overviews, ChatGPT and Perplexity, 3.8 times its closest competitor. Those are vendor-measured figures from client work, so treat them as proof the unit exists locally, not a benchmark to hit.
The industry is converging on the same shape, which matters when the room is asking whether the metric is real. Cision's PR Newswire launched an AEO and GEO report for APAC on Trajaan's search-intelligence data, reporting mentions (share of voice, ranking position, model-specific visibility), sources and the actual answers models give about an organisation. Three caveats belong with it: press release rather than reporting, APAC-wide with the Philippines never named, and Cision is a monitoring vendor and a Media Meter competitor.
When the Seller of the Exposure Also Supplies the Grade
Every proof layer on offer this week came from a party with a stake in the result, and the cleanest illustration arrived from retail media. Digiday reported that Walmart Connect began approaching brand clients directly, bypassing agencies, offering on-site brand lift studies before the holiday season, with three agency executives saying multiple clients were approached. Studies were offered on the basis of how much the advertiser spent through Walmart Connect, according to Anthony Costanzo of Mile Marker, who had at least four participating clients. The contested question is incrementality: did the campaign drive incremental sales, or did the retailer take credit for a purchase that would have happened anyway? Costanzo's description is the line to carry into any AI-visibility conversation, that retailers are "often grading their own homework". Walmart did not respond to Digiday's request for comment.
Count the graders in the AI-answer stack and the pattern repeats. The platform behind the volatility study sells visibility tracking. The wire service launching the APAC report distributes the releases its own report grades, and its executive calls that wire "the most effective lever". Closer to home, that Manila Times AI-readiness item is a free score published by the agency that fixes what the score finds, on a page carrying an "Advertisement" label and quoting only the vendor. The National Privacy Commission, separately, issued show-cause orders to Meta, Roblox, Reddit and Discord in September over Data Privacy Act registration requirements, a compliance action rather than AI regulation, but a reminder that the platforms generating your brand mentions are under examination themselves.
Described neutrally, these are useful products. As the only evidence in a board paper, they are a conflict of interest wearing a dashboard. A dated independent trail of what ran and what was said sits outside that problem, which is why real-time monitoring of Philippine media and social belongs beside any answer-level score, and why monitoring itself is shifting from clippings to citations.
Build AI Visibility Measurement a Board Can Check
Boards accept non-financial metrics. What they reject is a metric scored by the people selling the service. Comms measurement is moving that way anyway: writing for AMEC, Meltwater's Dino Delic argues measurement must move closer to decision-making as PR's strategic role grows, citing the Meltwater-sponsored 2026 USC Annenberg Global Communication Report, where 91% of US and 86% of international PR professionals said polarisation has increased PR's importance. No respondent count or fieldwork date is given there, so read those proportions as reported rather than verified, and note that we found no Philippine data on what local boards currently accept as proof. The board argument here is a global one applied locally.
One lesson from the last measurement fight is worth keeping: advertising value equivalency was cheap, comfortable and wrong, and AMEC's Barcelona Principles reject it outright as a measure of communications value. A share-of-answer figure supplied by the party selling the exposure is that error in newer packaging.
Philippine firms are meanwhile accelerating AI investment ahead of the proof, largely from fear of competitors pulling ahead, with IBM's country general manager Leo Capinpin noting local CEOs rank among the most decisive adopters while only a fraction hold a clear vision for advantage. The pressure is seasonal too. "Q4 is when advertisers are least willing to fund spend they cannot defend," PrograMetrix managing director Lacie Edgeman told Digiday.
So the specification is short. Take the baseline before you ask for the budget, because a baseline cannot be backdated. Read it weekly against a fixed question set in the language your buyers actually use. Report presence, share of answer and characterisation against named competitors, with the sentiment read labelled directional. And commission it from a party that owns nothing inside the result, which is why in-house corporate communications teams increasingly take this as a custom report rather than a vendor dashboard.
Key takeaways
- Fund AI presence as a brand channel. Assistant referrals ran at roughly 0.73% of volume in this week's studies, so a session-based business case fails on contact with the data.
- Read weekly. With 79% of question-and-assistant combinations changing a recommended brand inside four weeks, a snapshot reports the week rather than the brand.
- Keep the 88% AI Overview figure inside its sample: 400 US desktop keywords, three industries, clicks and conversions unmeasured. No verified Philippine prevalence figure exists.
- Set the baseline before the budget request, and label the sentiment read directional across Filipino, English and Taglish.
- Source one proof layer from a party that sells nothing inside the result, and say so in the board paper.
About Media Meter
Clip counts do not survive a boardroom, and neither does a score supplied by the seller. Media Meter builds decision-grade reporting on AMEC-aligned methodology, calibrated for the Philippine media landscape rather than imported from a global template.